Why computer vision pilots stall before the model does
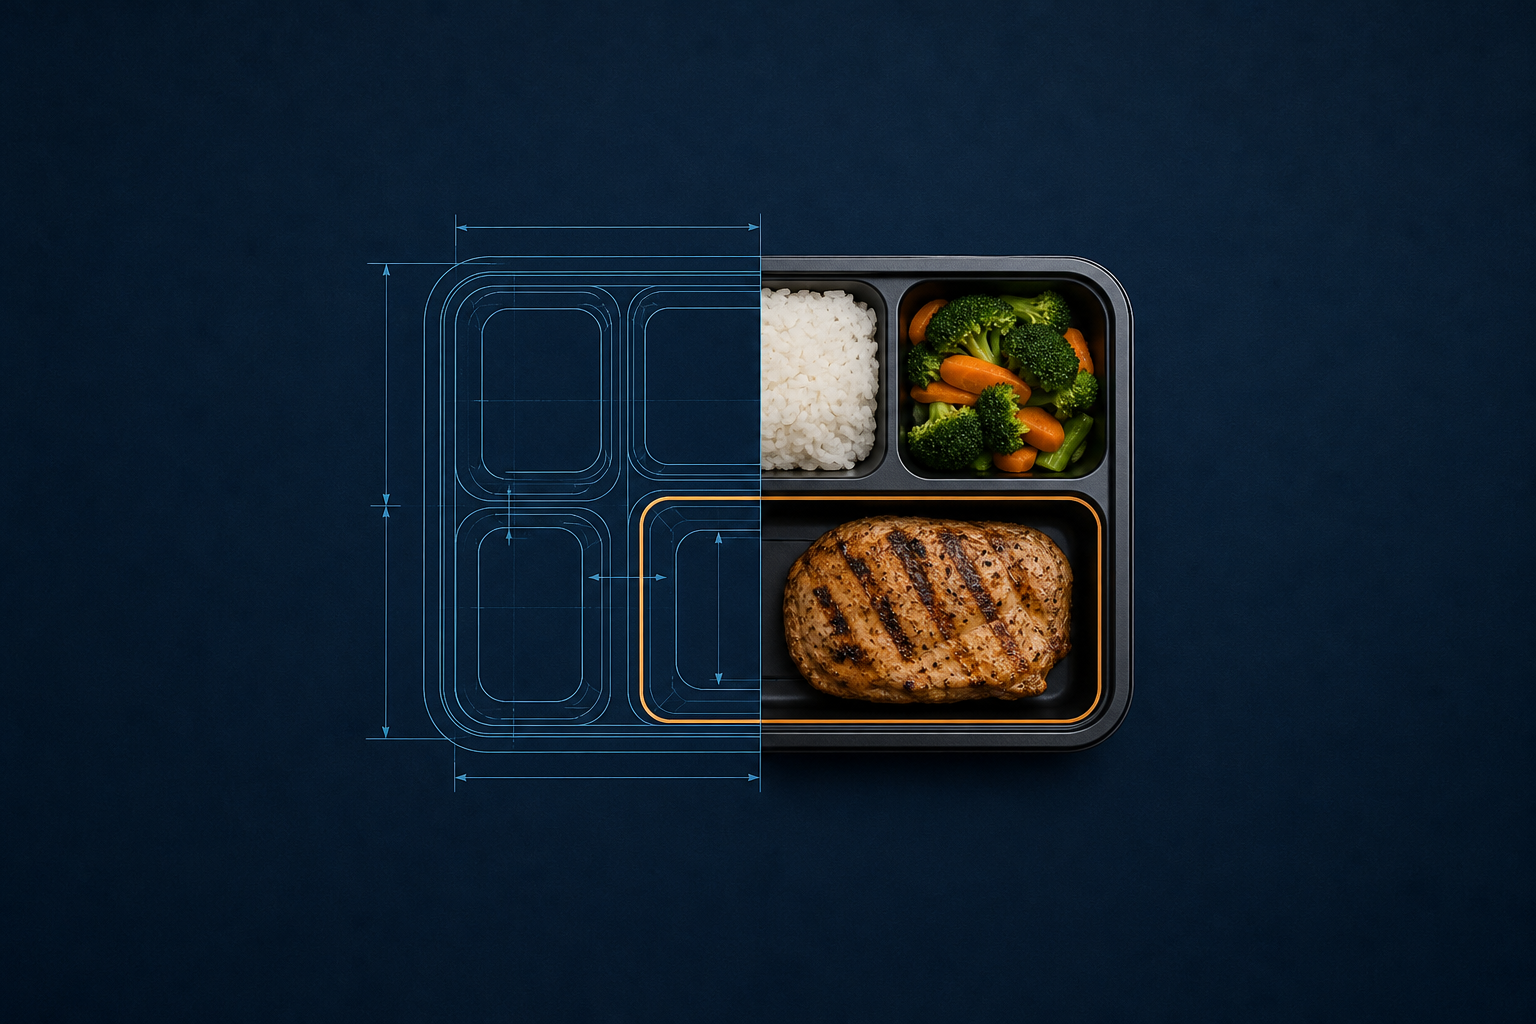
Why CV pilots stall

A catering operation decides to check trays with a camera. The model is chosen quickly, and a demonstration works. Then the pilot slows down. Someone has to photograph every dish, every tray layout and every kind of mistake, then label them all. The deadline arrives before the dataset does. The model was never the problem. … Read more
Where real data earns its place

Synthetic Data vs Real Data

Real production images are the most valuable data an inspection team has. They are also scarce, slow to collect and often restricted by customer or confidentiality terms. Synthetic data promises to relieve that pressure, and it can. As major platforms make synthetic images easy to produce, more teams will be tempted to train on them … Read more

Generating the image is easy. Checking the label is the work.

Labeling synthetic data

A convincing synthetic image of a parts kit or a meal tray is no longer hard to produce. Ten thousand of them, each labelled accurately enough to train an inspection model, is a different problem. That second problem decides whether a computer-vision project reaches the line. It is also the part of a synthetic data … Read more

The citation is the deliverable

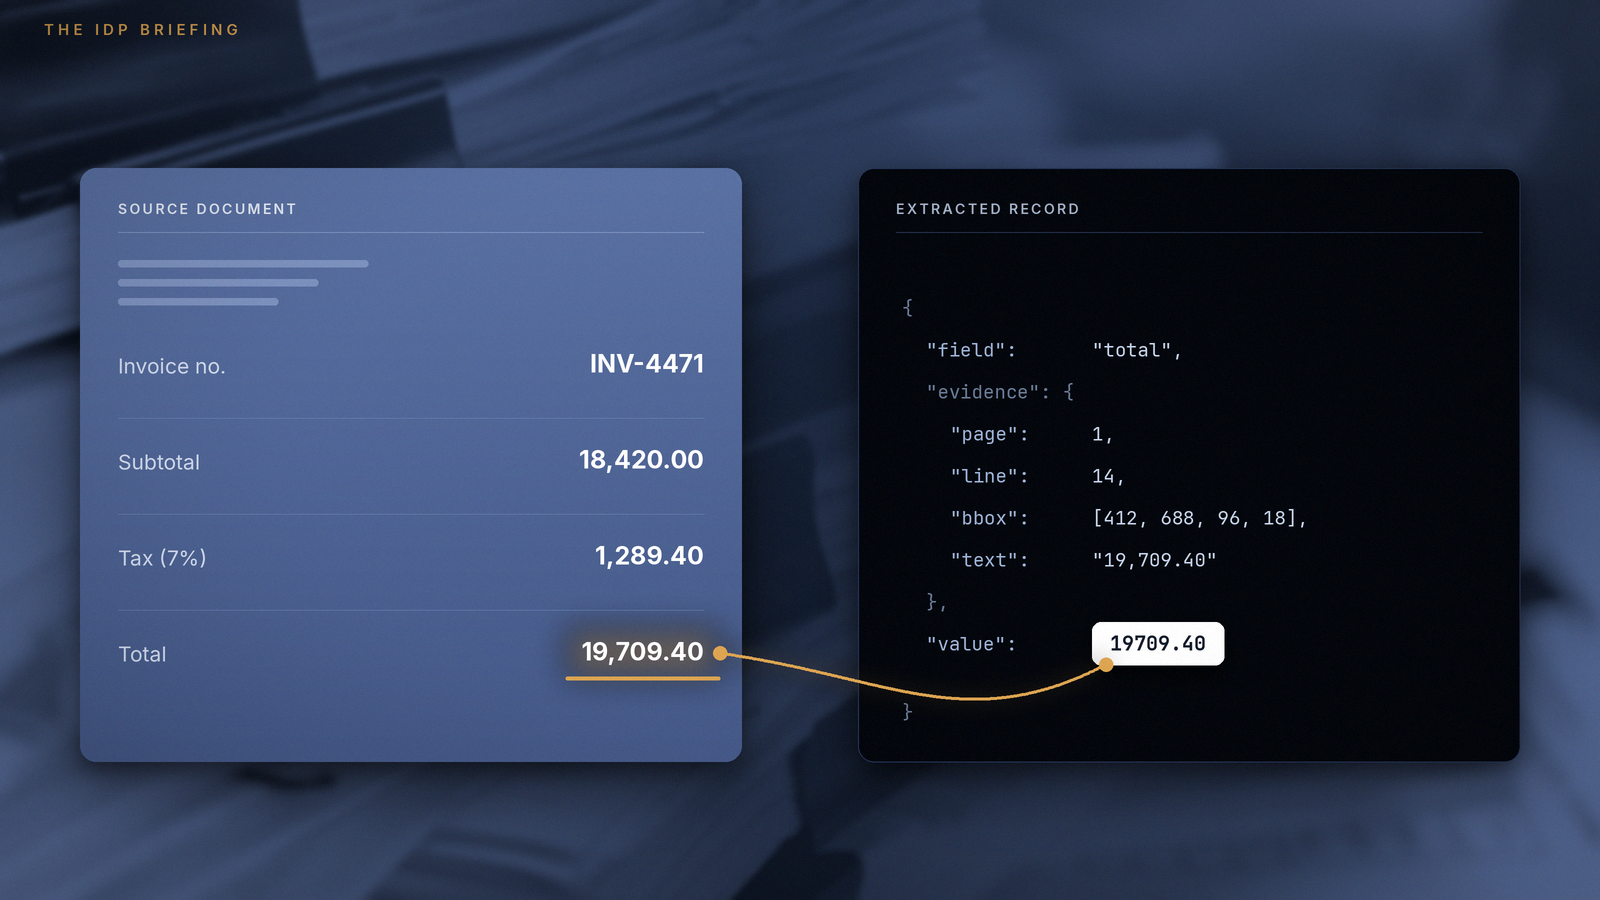
A source invoice beside its extracted JSON record, over a background of stacked clipped documents. The invoice total is underlined in gold and a gold line traces from it to the matching value in the record, which lists the page, line and region the value came from.

An extraction pipeline that cannot show its evidence has not finished the job. In certification work, a value on a certificate is only as good as the trail connecting it to the source document. In finance, a payment decision is only as defensible as the invoice line behind it. Yet most document AI systems deliver … Read more

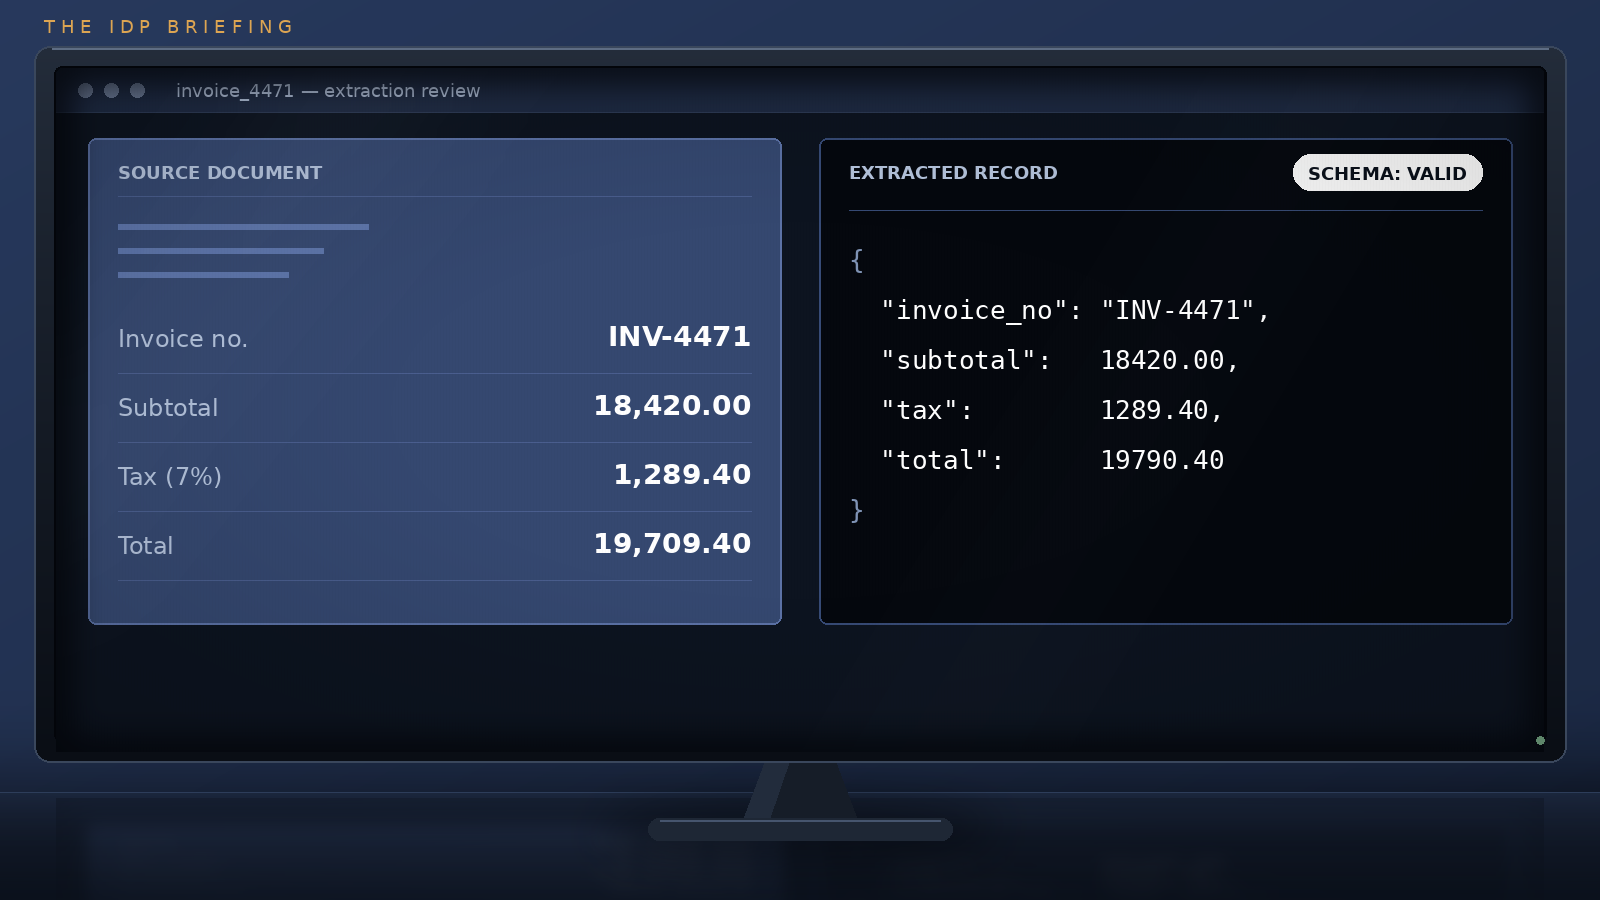
Valid JSON is not correct data

The most dangerous extraction error is the one that looks right. Modern document AI tools return clean, complete, schema-conformant output almost every time. Every field is present, every type is correct, and the record loads into the enterprise resource planning (ERP) system without complaint. Stakeholders see well-formed data and read it as accurate data. Our … Read more

Document AI has a new bottleneck, and it is not accuracy

Stacks of paper documents held together with binder clips, tinted deep navy.

Most intelligent document processing budgets are optimising the wrong half of the problem. Procurement teams compare extraction accuracy percentages, pilot teams demonstrate extraction quality, and vendors compete on extraction benchmarks. Yet the cost that decides whether a deployment pays for itself sits elsewhere: in the review queue, where people check what the models produced. Our … Read more