Most intelligent document processing budgets are optimising the wrong half of the problem. Procurement teams compare extraction accuracy percentages, pilot teams demonstrate extraction quality, and vendors compete on extraction benchmarks. Yet the cost that decides whether a deployment pays for itself sits elsewhere: in the review queue, where people check what the models produced. Our evaluation of document extraction pipelines reached a blunt conclusion. The binding constraint is no longer how well models read documents, but how efficiently humans can verify what the models claim to have read. This post sets out the evidence for that conclusion, and what it changes about how document AI is bought and budgeted.
Intelligent document processing (IDP) uses AI to turn documents into structured data that business systems can use. The documents are the unglamorous everyday kind: invoices, quotes, test reports and contracts. For decades, large teams of people have keyed data from documents into enterprise systems, often through outsourced processing operations. Large language models changed the economics of the reading step. A modern model arrives already knowing what an invoice is, collapsing the training effort older extraction systems required. That shift is why the question is live now, not five years ago. What is at stake is the shape of a large cost line. Organisations that process documents at volume are deciding whether to renew outsourcing contracts, buy extraction platforms, or build internal pipelines. They typically justify those decisions with accuracy claims. If the dominant cost has moved from extraction to verification, those justifications measure the wrong thing, and the promised savings quietly reappear as review headcount. This post is written for finance operations and shared services leaders who own that cost line. It will be equally recognisable to quality and certification directors and to transformation leaders accountable for automation programmes. The systems teams asked to make the tools work will recognise it too.
Document extraction got cheap; checking it did not
If verification now sets the cost, the first question is how that happened while everyone was watching accuracy. The answer is that the reading step improved faster than the checking step.
The steps of document processing have not changed: capture a document, read it, decide what matters, extract it, and pass it downstream. What changed is that general models now perform the middle steps well without task-specific training. The upfront build cost of an extraction pipeline fell accordingly.
The checking step did not move. A person still opens the source document, locates the evidence for each extracted value, and confirms it. For long documents, that is slow work: find the cited passage, compare it against the page, and judge whether surrounding context changes the meaning.
The consequence is an inversion. When extraction was expensive, review was a rounding error. Now that extraction is cheap, review is the line item. Industry buyer guides in 2026 make the same arithmetic plain. A pipeline that clears 95 per cent of pages untouched still sends a million-page month to reviewers 50,000 times (Grooper, 2026). At 1,000 documents a day, 98 per cent accuracy still produces 20 daily failures (IDP-Software, 2026).
That inversion would matter less if better models could shrink the review queue on their own. The evidence suggests they cannot, which is where measurement becomes useful.
What a controlled evaluation of five document extractors showed
A fair test needs the same documents for every tool, with the correct answers fixed before any of them runs.
We evaluated five extraction approaches on a corpus of 39 synthetic business documents, 21 invoices and 18 quotes (Aicadium Phase 1 evaluation, 2026). The corpus was built so that every field had validated ground truth. Testing on synthetic documents with known answers allows exact scoring without exposing any confidential client material.
Four of the five approaches achieved perfect schema adherence, a score of 1.000: their output was always well-formed and structurally complete. The fifth failed structure visibly, validating on roughly one record in five. Field-level accuracy told a different story. Among the four whose output was structurally perfect, mean field scores still spread from 0.798 to 0.908; the approach that failed structure scored 0.680. The best performer on accuracy took 162.5 seconds per invoice; the fastest took 15.8 seconds and still scored 0.826.
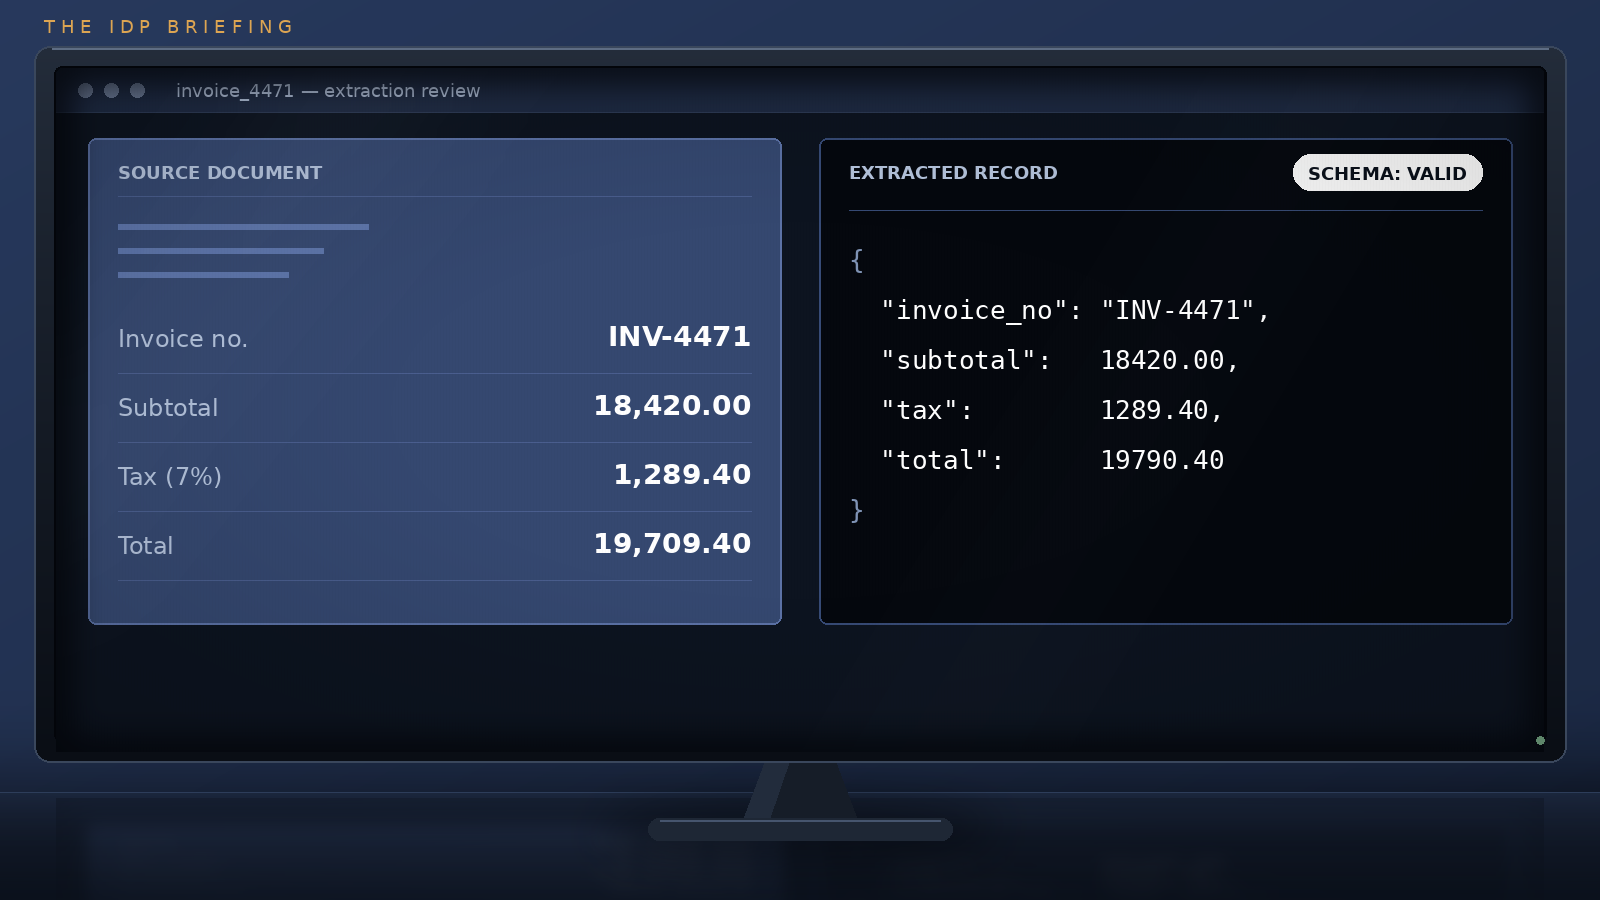
Two things follow. First, no approach was accurate enough to skip verification. A field score of 0.908 still leaves the equivalent of roughly one field in eleven short of ground truth, and nobody knows in advance which one. Second, the remaining errors are not visible in the output itself. A wrong value sits inside a perfectly formed record, indistinguishable from a right one.
So the review queue does not disappear at any accuracy level the current generation of tools can reach. The practical question becomes what an additional point of accuracy is worth, and the answer is uncomfortable.
Why higher accuracy does not shrink the review queue
An additional point of accuracy is worth less than the market assumes, because the model does not carry the consequences of its own mistakes.
When an extracted value is wrong, the cost lands on the organisation: a mispaid invoice, a wrongly certified result, a reconciliation dispute with a supplier. The vendor whose model produced the error carries none of that exposure. Responsible deployment therefore requires checking every value that matters, whatever the headline accuracy claims.
This is why moving from a high-accuracy model to an even higher-accuracy model produces limited practical benefit while verification remains manual. The reviewer still opens every document. The reviewer still locates every piece of evidence. Time per document barely moves.
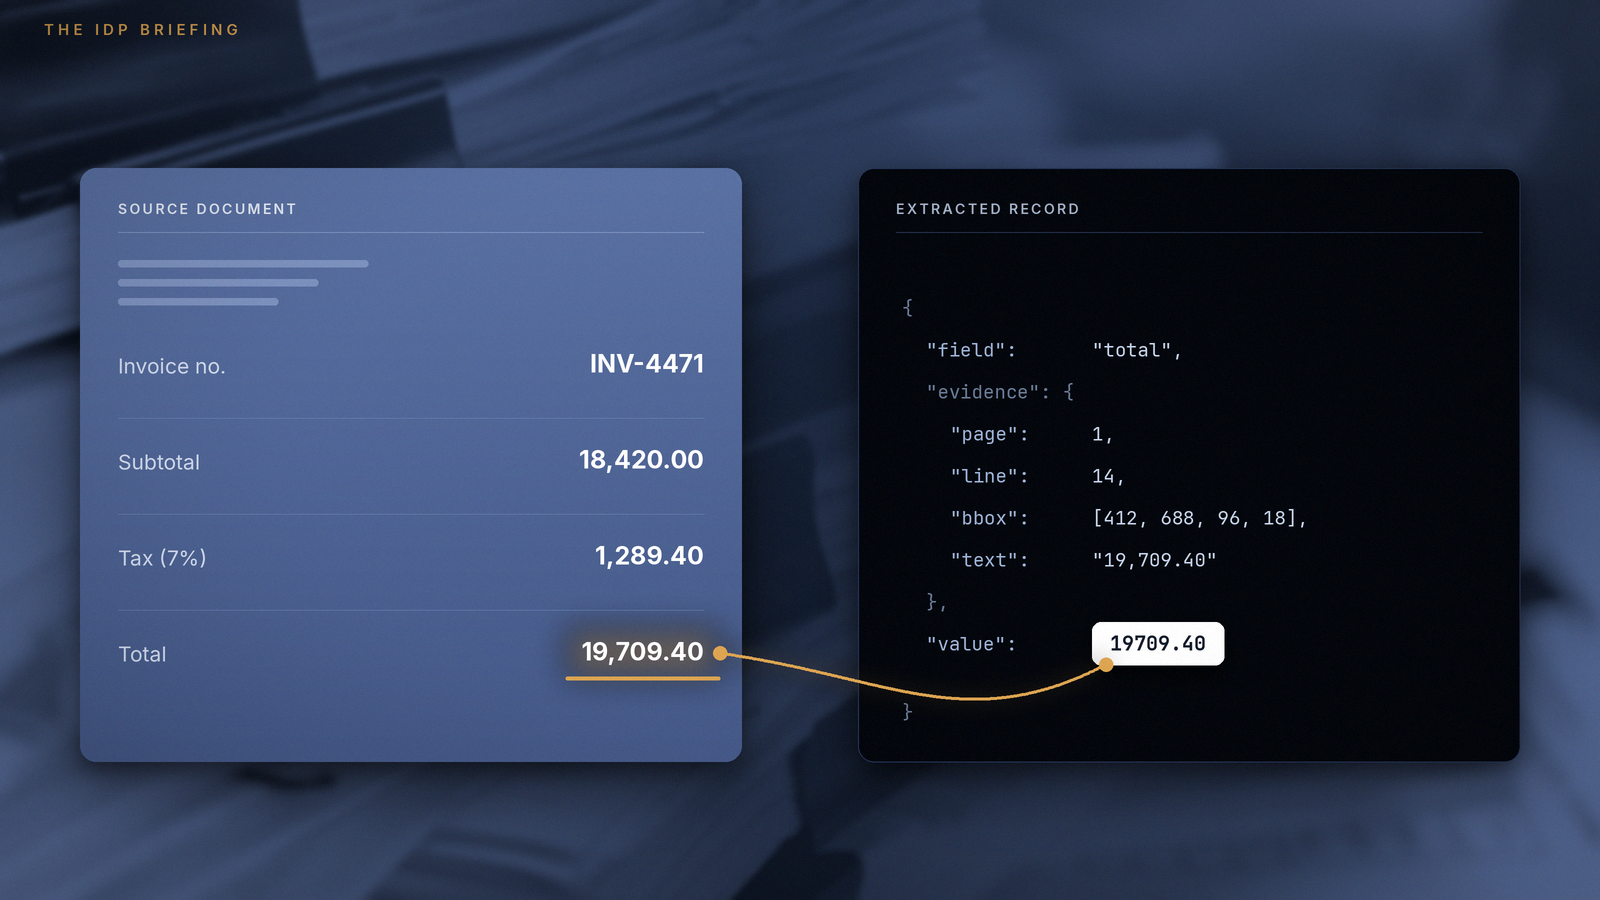
Compare that with improving the verification step itself. If each extracted field arrives with a citation pointing to its exact location in the source document, the reviewer stops searching and starts confirming. The same reviewer clears more documents per day, and the queue that sets the deployment cost gets shorter.
The efficiency gains compound at the workflow level, not the model level. Which is why the buying question needs to change from how accurate the extraction is to how fast a person can check it.
Budget for the review workflow, not the model
If the gains sit in the verification workflow, then budgets, pilots and vendor evaluations should be restructured around it. That reordering is concrete and starts with three changes.
First, cost the review queue explicitly. Most business cases for document AI model the extraction step and treat review as a residual. Reverse that. Estimate documents per month, fields per document, and minutes per verified field with and without visual evidence citations. The difference is the real saving on offer.
Second, change the pilot exit criteria. A pilot that demonstrates extraction quality has demonstrated the easy half. Require the pilot to run the verification workflow end to end: reviewers, citations, exception handling, and the audit trail. Deployments rarely fail at extraction; they stall where nobody designed the checking step.
Third, put verification questions at the top of vendor evaluations. Ask how each extracted value is traced to its source, what the reviewer sees when a value cannot be confirmed, and what happens when the source document itself contains an error. A system that silently corrects documents is destroying evidence.
None of this argues against accuracy. It argues that accuracy is now the qualifying criterion, not the deciding one. The deciding criterion is the cost of trust.
Closing
The economics of document AI inverted while the market was watching accuracy benchmarks. Extraction became cheap and capable; verification stayed manual and became the binding cost. Organisations that keep buying on accuracy percentages will keep discovering the gap in their review headcount. Organisations that evaluate the verification workflow first will capture the savings the technology genuinely offers. The measured evidence behind this argument is set out in the next post in this series, Valid JSON is not correct data, and the design standard that follows from it in the third, The citation is the deliverable.