The honest version of the AI marketing story includes the edits.
Most accounts of AI in marketing skip that part, and the omission has done real damage to the conversation. Buyers are shown finished output and invited to infer that it arrived finished. When their own first attempts do not, the reasonable conclusion is that the technology is not ready, when the actual problem is that nobody described the workflow accurately.
What is at stake is where a marketing team places its people. Every hour saved in drafting has to go somewhere, and if it is not deliberately reinvested in review, it is simply absorbed by a longer queue of unreviewed drafts. Teams that treat AI as a way to remove the review step tend to find quality falls and, more expensively, that they can no longer say why any given asset was approved. Teams that treat it as a way to afford a better review step get something they did not have before.
This is written for marketing leaders deciding how to staff and sequence AI-assisted production. It will also matter to legal, compliance, and brand colleagues, who usually inherit the consequences of a weak gate and are rarely consulted when one is designed.
When Aicadium built SPECTRUM, our AI campaign engine, the output did not arrive publication-perfect. It arrived at seven or eight out of ten, reliably and fast. The design question that mattered was where humans should intervene. Our answer did not replace the review gate marketers already have. It made that gate stronger.
SPECTRUM pairs AI generation with mandatory human checkpoints and an automated evaluation gate. The copy it produces reaches publication quality after as little as one round of human editing.
Set the expectation at seven out of ten
That “seven or eight out of ten” is doing a lot of work in the paragraph above, so it is worth being precise about what it measures.
AI-generated campaign copy is consistently good and rarely finished. In our runs, first-pass output landed at seven to eight out of ten. That is the score our copy evaluator assigns across its full set of checks (below). Structurally sound, on-brief, persona-appropriate, and still in need of human editing before publication. Leaders who expect ten will be disappointed. Leaders who plan for the editing round get near-baseline quality in a fraction of the time.
The corollary is that review capacity becomes the bottleneck, not generation capacity. When drafts arrive in minutes, the queue forms at the editor’s desk. Designing the review layer, therefore, deserves as much attention as choosing the model, and it rarely gets it. Marketing tool buying decisions are made on generation quality, which is the part vendors demonstrate, while the constraint that will actually govern your throughput sits downstream of anything shown in a demo.
What AI adds to the review gate
If review is the constraint, the useful question is not how to review faster. It is what a machine can check before a person spends attention on it.
Marketers already have review gates. What changes with AI is what the gate can check automatically, before a human ever looks. Because generation is fast, we could also afford to sequence strictly rather than run copy and creative in parallel. Finish the words, review the words, then let the words direct the creative. Moving from a parallel workflow to a structured sequence removes the expensive rework that happens when late copy changes ripple through the finished design.
That sequencing is only affordable because redrafting is cheap. Under the manual baseline, waiting for finished copy before briefing creative would have added a week to the calendar, which is precisely why so many teams run the two tracks in parallel and absorb the rework.
Every AI step in SPECTRUM gives the marketer the same four controls over the output: review, reject, improve, or approve. Nothing advances on the machine’s authority alone.
Automated evaluation before human review
Those four controls describe what a person can do at each step. The automated gate determines what reaches them in the first place.
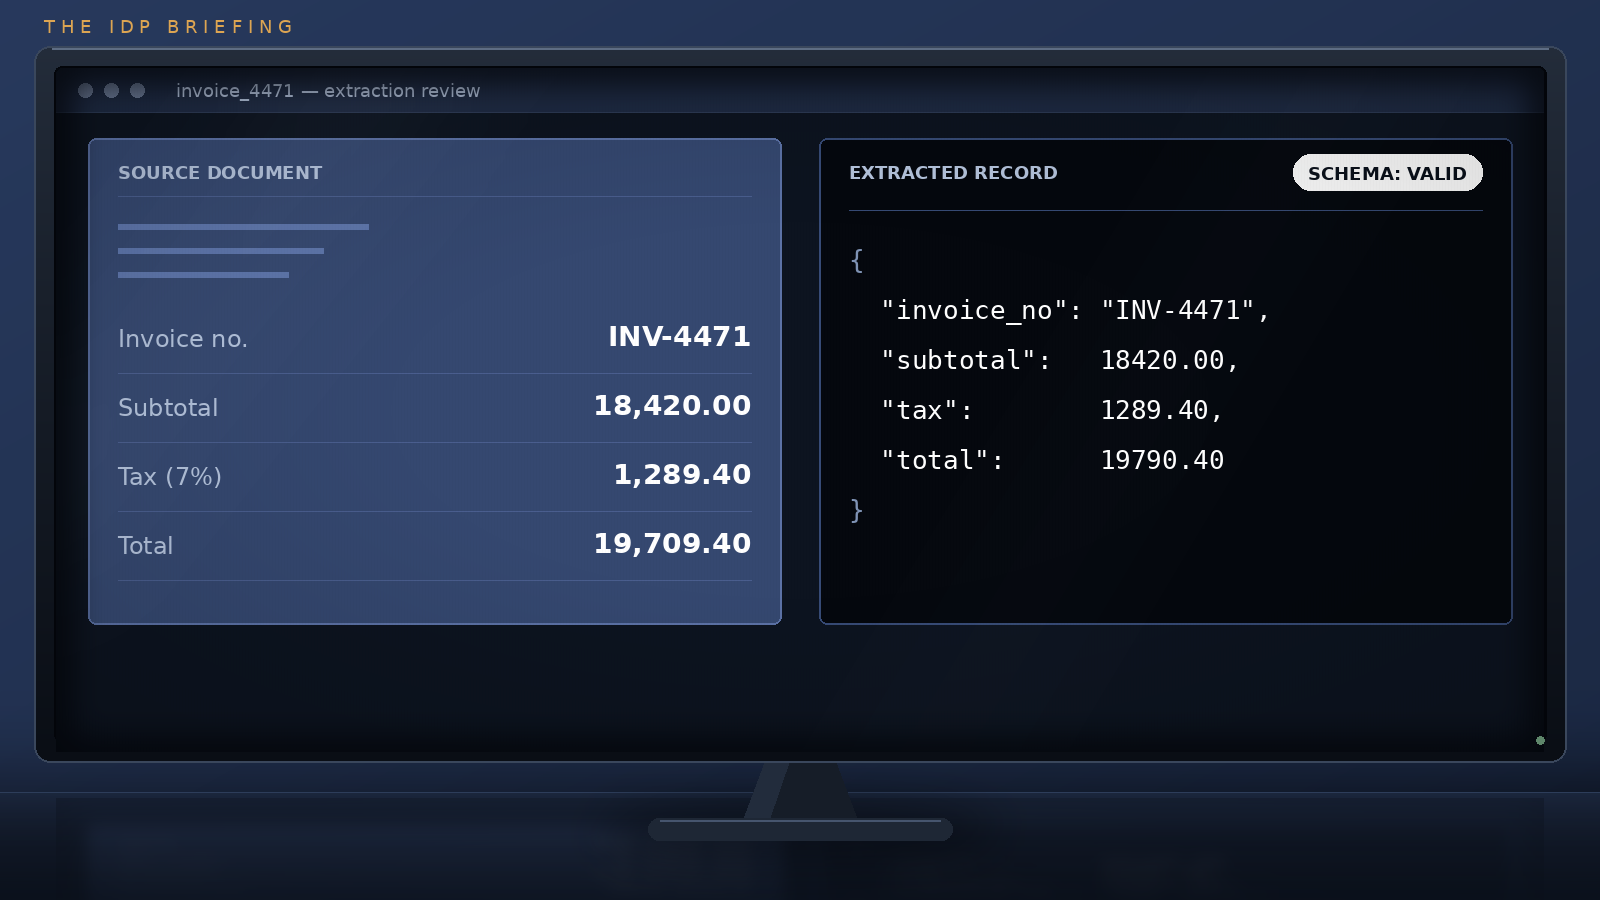
Every piece of copy passes through an automated evaluation step, our copy-evaluator skill, before it reaches a person. It scores the draft across several dimensions. Mechanical quality covers spelling, grammar, sentence length and banned hype vocabulary. Brand voice checks compliance with our editorial playbook. Persona fit asks whether the argument, register, and proof match the intended reader. Machine readability gauges how well AI answer engines will parse and cite the piece. Fact verification traces every verifiable claim to a source. Bias and inclusivity flags non-inclusive or bias-coded language. And a human-sounding voice check catches the machine tells that make copy read as AI-generated.
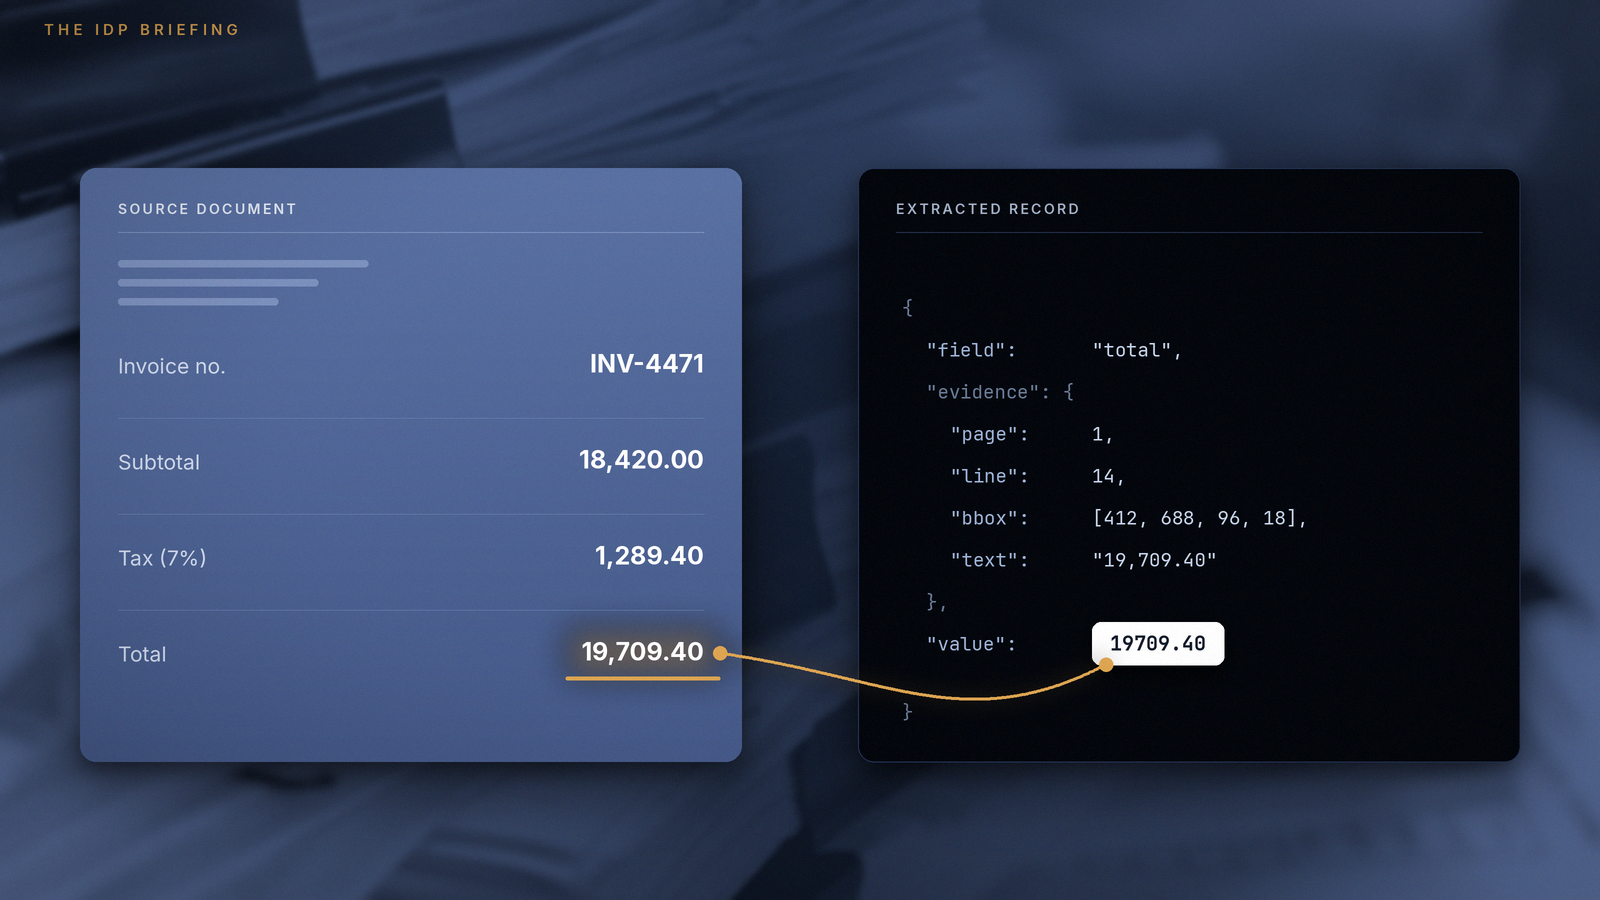
The strictest rule concerns facts, and any verifiable claim without a traceable source is flagged as critical and blocks publication. Language models state falsehoods fluently, so a fact register turned out to be the single highest-value control in our pipeline. That register lists every statistic, date and comparative, each with a source.
The following is an example from our own testing. A draft blog cited a percentage for time marketers spend on repetitive tasks, a figure that circulates widely in vendor decks. The evaluator flagged it as unsourced. When we went looking, no primary source survived scrutiny, so the claim was rescoped to our own team’s measured experience. The published sentence was weaker as rhetoric and stronger as evidence. That trade is the point of the gate.
It is also the case for running the check on everything rather than on samples. A human reviewer under time pressure will not stop to trace a statistic that reads plausibly and matches what they have seen elsewhere. That is exactly the kind of claim the register catches.
Where do humans stay mandatory?
At approval points and at ambiguity. Persona selection, copy approval before creative, fact sign-off and the final stakeholder review are human decisions by design. These are the judgment calls a marketing leader makes daily, such as whether the message is right for this audience and on-brand.
Does the human layer erase the speed gains?
No. In our measurements, generation takes minutes, and structured review takes on the order of an hour to work through a campaign’s outputs. The manual baseline for the same creation work is about two weeks. That work is planning, research, copywriting, a first round of edits, and the creative brief. The gates consume a small fraction of the time they protect.
The takeaway: rigour is the feature
Read together, those checkpoints describe a gate that is not a tax on the speed gain. It is what the speed gain buys.
Human-in-the-loop is the design, not a concession to imperfect AI. What AI adds to the review gate is a consistent, auditable standard applied to every asset. The copy-evaluator skill produces a scorecard for each piece, listing the scores, the fact-check register and the flagged issues. Quality becomes something you can inspect and defend, rather than a matter of who reviewed it that day. Marketing leaders adopting AI generation should invest first in their checkpoints. Expectation-setting, evaluation criteria, and fact verification are where trust in the whole system is built.